Constraints and quality
This chapter covers the rules the design has to live within, the quality goals it's judged by, what we've measured so far, and the risks we know about.
Constraints
| # | Constraint | Why | Where it bites |
|---|---|---|---|
| C1 | Engine in TypeScript | Shared by CLI, language server and extension (ADR-001) | Raw parse speed, binary size |
| C2 | Python parsed with tree-sitter, WASM build | Portable across Bun, Node and every target (ADR-002) | About 12 ms of WASM start-up per process |
| C3 | Distributed as a Bun single-file executable | No runtime prerequisites; installs as a dev dependency (ADR-003) | 66 to 90 MB per binary depending on the platform (85 MB for Linux x64), almost all of it the Bun runtime |
| C4 | Never import or execute user code | Deterministic, safe on untrusted repos, no venv needed | Only dynamic imports with a literal target can be checked (INW011); a computed target is reported as unverifiable in inner layers, not resolved |
| C5 | No network access at check time | Works offline, in sandboxes and in locked-down CI | Rule packs must ship inside the binary or the repo |
| C6 | Config in pyproject.toml under [tool.inwards] |
Python convention (ADR-005) | Protecting the config needs hooks or CODEOWNERS |
| C7 | Output contract inwards/diagnostics@1 is additive only |
Agents and scripts depend on it (ADR-007) | Renames need a new major schema |
| C8 | Linux, macOS and Windows on x64 and arm64 | Where agents and CI run | Path handling, CRLF, the release verify matrix |
Quality goals
Ranked. When two goals conflict, the higher one wins.
| Rank | Goal | Scenario | Measure |
|---|---|---|---|
| 1 | No false negatives | An agent hides a forbidden import in a function, behind TYPE_CHECKING, via a relative path or a package import |
Every form is reported, including shop . infrastructure with spaces, a backslash inside the name, NFKC identifiers and symlinked aliases of a layer. Dynamic imports with constant targets (importlib.import_module, __import__, exec) are reported as INW011, and computed targets in inner layers as unverifiable INW011. Loaders are followed through aliases, assignments, attributes, functools.partial and names bound inside exec, and constant targets are folded; chapter 3 lists the known gaps. Unit tests plus the prescan differential test (0 misses on 92,448 generated and 1,921 stdlib files, dynamic imports included, and nightly on 6,543 files from five open-source services) |
| 2 | Agent-loop latency | A hook checks one edited file | p95 < 100 ms wall time, process start included |
| 3 | Actionable for agents | An agent gets INW001 | It fixes the violation within one retry in ≥ 80 % of cases (measured with design partners, see chapter 2) |
| 4 | Deterministic | Same repo, same config, two runs | Identical diagnostics in identical order. Only the timing fields in the summary (durationMs) change |
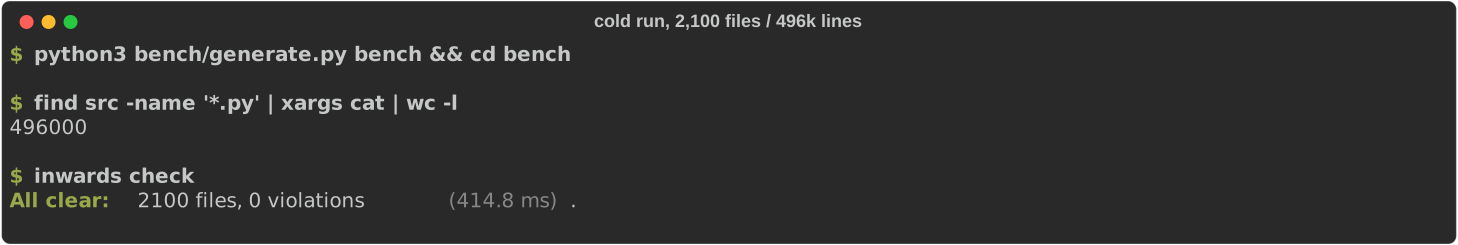
| 5 | Full-repo throughput | CI checks a 500k-line repo cold | 0.33 s for the 496,000-line synthetic repo and 0.87 s for saleor's 848,000 lines with four threads (#61, #281). Target < 300 ms with threads and cache |
| 6 | Easy to adopt | New team, existing codebase | One command wires in the agent (inwards init). The Stop gate checks only what a session changed, and in a changed file only what is new since the session started, so old violations don't block; the baseline (UC6, #33) will cover the rest |
Correctness sits above speed on purpose. A guardrail that sometimes stays silent teaches the agent that the wrong move is fine, and that's worse than no guardrail.
Measurements
All numbers come from the scaffold in this repository. Nothing here is projected. They were measured during M0; the spot check below shows how they have moved since.
Setup. A laptop, Bun 1.4.2, inwards-linux-x64 built by scripts/build-binaries.ts. Everything ran on one thread; the worker threads came later (#61). The laptop was in normal desktop use (load average around 2 to 3), so these are realistic numbers rather than best-case ones.
Synthetic repo. 2,100 Python files, 496,000 lines, 8.0 MB, four layers with eight first-party imports and forty small functions per module. bench/generate.py rebuilds it exactly (fixed random seed). With --legacy it adds an outer legacy layer that every module imports, so each of the 2,000 modules has one violation: the legacy codebase that chapter 3's cost model times with a full baseline.
Regression gate. Every pull request runs .github/workflows/bench.yml. It builds the base branch and the PR, runs both on the synthetic repo in alternation (40 hook runs on one file, 12 full checks), and fails when the PR is more than 20% slower on any metric, or when either build fails a run (the synthetic repo is clean, so every run must exit 0). Each side is built with its own .bun-version, so a Bun upgrade is measured too. The change is the median of per-pair ratios, so load that drifts during the job cancels out within a pair. The full checks run with INWARDS_NO_CACHE=1, so the gate measures the work, not the extraction cache. A fourth gated metric times the PostToolUse hook on a generated 4,482-line module with two old violations, in a small project of its own, changed before every run as an agent's edit does (bench/large-file.ts, #122). Like polar's file, its docstring mentions an import, so the prescan refuses it and every check parses all of it. A head-only table times the same hook one-shot and through the daemon, against the 100 ms budget and the 50 ms target. A second table, head only and not gated, times the full check with no cache, an empty cache (moved aside before each run) and a warm one. A third, head only and not gated either, times the PostToolUse hook one-shot and through inwards daemon in alternation and reports the daemon's p95 against #60's 50 ms target. Every other run sets INWARDS_DAEMON=0, so both builds run one-shot. The gate covers hook and full-check time only, not memory, start-up or binary size. The job summary shows p50/p95 for both builds (with 12 full runs, p95 is the slowest one) and the runner it ran on, and the raw samples are kept as an artifact. Locally, a build made 30% slower fails the gate, and ten runs of identical builds didn't fail it once (bench/compare.ts, bench/test/compare.test.ts).
Real-repo corpus. Stdlib and synthetic code don't look like a FastAPI or Django service, so .github/workflows/corpus.yml runs every night (and on any PR that changes the corpus or prescan-diff.ts) on five open-source repos pinned by commit in bench/corpus.json. bench/corpus.ts fetches each one shallow, only the pinned commit, and for three of them only the service directory (backend/, server/, saleor/; sparse cone mode also brings the files at the repo's top level), about 40 MB in all. It runs the prescan differential test on every .py file in the checkout and times the compiled binary: 5 full checks and 20 runs of inwards check --no-cache <file> on one file per repo, after one warm-up each. The one-file runs read no cache, as the hooks don't; until #122 they read the cache the full checks had just filled, which hid the parse. None of these repos has a [tool.inwards] table, so the manifest gives each one a layering of ours (written to inwards-corpus.toml in the checkout and passed with --config). The violation counts come from that layering and say nothing about the projects. The job fails when the prescan misses an import, when a checkout's .py count differs from the manifest (a broken fetch would otherwise shrink the corpus), or when inwards check exits with anything but 0 or 1. A repo that still fails to fetch after three attempts, or whose run fails, is recorded in the results and fails the job; the other repos still run. The table goes to the job summary and the raw samples to the corpus-result artifact.
| Repo | License | Why it's in | Checked with |
|---|---|---|---|
fastapi/full-stack-fastapi-template cb740b6, backend/ |
MIT | FastAPI's official template, the layout many small services start from | core, services, api |
ivan-borovets/fastapi-clean-example 9271723 |
MIT | Clean architecture on FastAPI | core, outbound, inbound, main |
pgorecki/python-ddd 429cd4b |
MIT | DDD modular monolith, three bounded contexts | domain, application, infrastructure, interface |
polarsource/polar cfae1ba, server/ |
Apache-2.0 | A large FastAPI service in production, about 70 feature packages | kit, models, features, entrypoints |
saleor/saleor 5ff5648, saleor/ |
BSD-3-Clause | A large Django service, bigger than the synthetic repo | core, apps, api |
First run, on the laptop described under Setup (load average 3 to 4), inwards 0.1.0:
| Repo | .py files |
Lines | Prescan refused | Prescan missed | Full check p50 / max | One file p50 / p95 | Violations |
|---|---|---|---|---|---|---|---|
| full-stack-fastapi-template | 40 | 2,685 | 0 | 0 | 59 / 60 ms | 46 / 51 ms | 8 |
| fastapi-clean-example | 209 | 6,764 | 0 | 0 | 80 / 87 ms | 46 / 49 ms | 2 |
| python-ddd | 139 | 5,852 | 0 | 0 | 82 / 87 ms | 43 / 45 ms | 10 |
| polar | 1,831 | 435,688 | 22 (1.2 %) | 0 | 1.16 / 1.37 s | 124 / 142 ms | 494 |
| saleor | 4,324 | 847,875 | 13 (0.3 %) | 0 | 1.84 / 1.89 s | 59 / 62 ms | 758 |
The Violations column is from a later run (the INW010 review in #45), after INW005 and INW010 landed; saleor's count includes INW010's four broken imports.
Two things the synthetic repo didn't show. inwards check on polar's subscription/service.py (4,482 lines, 175 KB, two violations) takes about 125 ms here and 280 ms on a GitHub runner (AMD EPYC 7763, 2 cores), over the 100 ms budget; a small file in the same repo takes about 55 ms. The budget is written for the Claude Code hook, which runs the same one-file check (runCheck on the edited file) after reading its payload, so the hook can only be slower. Tracked in #122. Rerun locally after bytecode compilation (#118) cut every one-file check by 20 to 40 ms: polar's file now takes 83 / 90 ms (p50 / p95), saleor's 27 / 30 ms. The hook on polar's file, which checks it twice, stayed over budget until #122 parsed the second check incrementally (below). And a cold full check of saleor's 848,000 lines takes 1.8 s on one core (2.5 s on the GitHub runner), where the 496,000-line synthetic repo takes 0.4 s.
Results
| Scenario | Result | Budget | Status |
|---|---|---|---|
| Cold full run, naive full parse (first design) | 7.5 s | < 1 s | rejected, led to ADR-004 |
| Cold full run, import skeleton | 0.63 to 1.17 s (runs across two sessions) | < 1 s | at the edge |
| Warm full run, extraction cache (#56) | p50 0.46 s, against 1.25 s uncached in the same run (3.0 times faster, machine under load) | n/a | |
Cold whole-project check with the import cycle search (#54, cycles = ["modules"]), 8 alternating runs each with INWARDS_NO_CACHE=1, load average about 1.1 |
median 1.51 s, against 1.35 s for the same check without it; most modules sit in cyclic groups, and every file in them is confirmed (a full parse of each would take about 7 s) | < 1 s | over budget on this machine with or without the search; the 0.40 to 0.44 s spot check below was on a quiet machine |
| Single file, wall time incl. process start (30 runs) | p50 48.6 ms, p95 80.4 ms | p95 < 100 ms | with little headroom |
| Single file, engine time reported by the CLI | 16 to 30 ms | n/a | |
inwards --version (process start only) |
about 10 ms | n/a | |
| Module index + importers of one module, cold, one core (2,100 files, fresh process) | 0.1 s index + 0.65 to 0.74 s for the importers (684 files mention m0: the synthetic names are the worst case for the text filter). Since #44 the index reads nothing up front: building it takes 17 to 21 ms, listing the 2,100 modules 25 to 32 ms, and the importers read the files they need, 0.53 to 0.71 s in total (0.58 to 0.66 s for the eager index it replaced) |
< 1 s | |
| Prescan refusals on the CPython 3.14 stdlib | 8.3 % of 1,921 files | lower is faster | |
| Prescan missed imports on the same corpus | 0 | 0 | |
| Prescan missed imports on the real-repo corpus (6,543 files, five services) | 0 | 0 | |
| Peak memory, full synthetic run | about 120 MB RSS | n/a | |
| Binary size, Linux x64 | 82 MB | n/a | large |
Spot check on 0.1.0 (2026-09-26)
Same laptop, a fresh inwards-linux-x64 build, load average about 1, measured twice independently with the same result. Single-file check on the example app, 30 runs: p50 37 ms, p95 40 ms wall time, 14 ms engine time. inwards --version: about 19 ms, up from about 10 ms. Cold full run on the synthetic repo, 5 runs: 0.40 to 0.44 s. Peak RSS about 207 MB, up from about 120 MB. Binary size is unchanged at 82 MB (79 MiB). The bytecode spike below halved start-up after this check, and the start-up breakdown was redone with it. The CI benchmark (#29) now fails any PR that makes the hook or the full check more than 20% slower; it doesn't track memory, start-up or binary size.
Spike: bytecode and minification
#39 asked whether bun build --compile flags cut start-up or binary size. Since then scripts/build-binaries.ts builds with --bytecode --format=esm on top of --minify --sourcemap=linked.
Method. Six variants of inwards-linux-x64 from one commit, Bun 1.4.2, the same laptop as above. Start-up: 200 rounds of inwards --version, every variant once per round in rotating order. Hook and full check: bench/compare.ts with the current build as base, 100 hook runs and 20 full checks per side, change as the median of per-pair ratios. Peak RSS: /usr/bin/time -f %M, median of 5 runs. MB means 10^6 bytes throughout. The load average was 2 to 6 during the runs, so trust the ratios more than the absolute milliseconds; a base-against-base run moved 0.2% (hook) and 0.6% (full).
| Variant | Size (Linux x64) | inwards --version p50 / p95 |
Hook, one file | Full check | Peak RSS, full / hook |
|---|---|---|---|---|---|
Before: --minify --sourcemap=linked |
82.4 MB (37.1 MB gzipped) | 22.3 / 30.9 ms | base | base | 202 / 54 MB |
Without --minify |
82.6 MB | +3.0% | +3.7% | +1.5% | 203 MB full |
| Without the sourcemap | 82.2 MB | -0.7% | not run | not run | |
No .env or bunfig.toml autoload |
82.4 MB | -0.8% | -3.0% | +0.6% | 205 MB full |
--bytecode (CJS, Bun's default with it) |
85.0 MB | 10.0 / 14.6 ms (-56%) | -45.6% | -5.6% | 205 / 55 MB |
--bytecode --format=esm (adopted) |
84.9 MB (38.4 MB gzipped) | 10.5 / 14.3 ms (-53%) | -45.4% | -7.0% | 205 / 56 MB |
A repeat with the committed build and bench/compare.ts defaults (40 hook runs, 12 full checks) gave hook p50 / p95 64.4 / 73.6 ms before and 32.6 / 37.4 ms after (-48.0%), and full check -9.9%. A second start-up run gave 25.0 ms before and 10.8 ms after. On the example app, 60 alternating single-file checks: p50 58.7 → 30.3 ms and p95 77.7 → 39.5 ms wall time, and the engine's own time fell from 21.7 to 14.5 ms, because the engine and web-tree-sitter's JS glue no longer get parsed on first call either.
- Bytecode is the win. It moves JS parsing from every start to build time. It costs 2.5 MB per binary (1.3 MB gzipped) and 1 to 3 MB of RSS.
- Size can't be fixed with flags. Everything Inwards adds is under 1 MB (176 KB of minified JS, 0.67 MB of WASM); the rest is the Bun runtime. Minification was already on and saves 0.1 MB; the sourcemap costs 0.26 MB and keeps stack traces pointing at the TypeScript source, so it stays.
- ESM, not CJS. Head to head the two bytecode builds differ by +2.9% (hook) and +2.2% (full), within noise. ESM keeps the module semantics the binary had before.
- Checked. The 350 tests pass against the compiled binary (
INWARDS_BIN=dist/inwards-linux-x64 bun test), so do--versionand both embedded.wasmfiles (every check parses). A test program built the same way still reports the TypeScript line of a thrown error through the linked sourcemap. All six targets cross-compile, and the musl build checks the synthetic repo inside Alpine. CI's test matrix builds and tests the macOS and Windows binaries natively. - Not tried. Bun's current docs list
--compile-jit-policyand--bytecode-order(profile-guided bytecode layout); Bun 1.4.2'sbun buildhas neither.--bytecode-depth, which 1.4.2 has, wasn't measured. Worth a look after a Bun upgrade.
Where a single-file check spends its time
Redone in the bytecode spike, with the bytecode build. Process start is inwards --version. The grammar and parse figures come from a script compiled the same way that times reading the embedded .wasm files, Parser.init, Language.load and one parse of shop/domain/order.py from the example app, median of 30 runs. "Config + I/O + rules" is the engine time the CLI reports (14.5 ms) minus those, not a measurement.
---
config:
  theme: base
  themeVariables:
    pieSectionTextColor: "#ffffff"
    pieTitleTextColor: "#6b7580"
    pieStrokeColor: "#ffffff"
    pieOpacity: "1"
    pie1: "#084e65"
    pie2: "#0b6784"
    pie3: "#2f7f99"
    pie4: "#3e4852"
    pie5: "#56616c"
    pie6: "#6b7580"
---
pie showData
    title One-file check, about 25 ms of work (engine + start-up)
    "Process start (Bun runtime)" : 10.5
    "WASM runtime init" : 7.8
    "Python grammar load (447 KB)" : 2.7
    "Parsing the file (first parse)" : 2
    "Config + file I/O + rules (remainder)" : 1.5
    "Reading the embedded .wasm files" : 0.5
In M0 the same check was about 30 ms of work: 10 ms process start, 12 ms WASM init, 3.5 ms grammar load, 1 ms parse and 3.5 ms remainder, all without bytecode. Parsing the file is still a small slice. About 85% of the cost is paying the same start-up price on every hook call. The wall-time p50 of 30 ms sits above this 25 ms of work because the harness spawns the process, and an agent's hook runner pays that too.
This changes the performance roadmap. For the agent loop, parse speed doesn't matter much. Start-up does.
Spike: a resident process
#59 asked whether the hooks and the language server should share one resident process, and what the hooks would gain from one. The decision is ADR-039.
Method. One arm64 laptop on macOS, Bun 1.4.2, inwards-darwin-arm64 built by scripts/build-binaries.ts from aede2ab. Other agents were working on the machine, so the load average was 5 to 7; trust the differences more than the absolute numbers. The project is examples/broken-app with a generated shop/domain/big.py added: 4,492 lines, 114 KB, two INW001 violations, close to polar's file in #122 (4,482 lines, two violations). The hook input is the Claude Code PostToolUse fixture pointed at each file, after a SessionStart, so both files' violations count as old. Each case ran 80 times (60 for PreToolUse and Stop), every case once per round in rotating order, after one warm-up; check runs set INWARDS_NO_CACHE=1. The resident process is a throwaway Bun script, run from source, that serves today's hookClaudeCode warm behind a Unix socket, with a per-request Runtime and buffered Streams; the client is a 10-line program compiled like the binary. "With caches" adds an in-memory extraction cache keyed by content and keeps git cat-file blob answers, which name a commit, for the life of the process.
| Scenario | p50 | p95 |
|---|---|---|
| An empty program compiled like the binary | 16.6 ms | 17.4 ms |
inwards --version |
15.5 ms | 16.9 ms |
| The spike client with no daemon listening | 13.1 ms | 14.1 ms |
inwards check on the 13-line order.py |
27.7 ms | 30.6 ms |
inwards check on big.py |
70.8 ms | 77.3 ms |
The same two checks warm, in one process (runCheck, 200 runs) |
0.8 / 29.8 ms | 1.4 / 31.3 ms |
| PreToolUse, one-shot | 16.8 ms | 17.6 ms |
| Stop over both files, one-shot | 141.1 ms | 149.6 ms |
PostToolUse order.py: one-shot |
46.6 ms | 50.2 ms |
PostToolUse order.py: resident |
32.3 ms | 35.2 ms |
PostToolUse order.py: resident, with caches |
17.2 ms | 19.8 ms |
PostToolUse big.py: one-shot |
119.9 ms | 151.6 ms |
PostToolUse big.py: resident |
91.1 ms | 97.7 ms |
PostToolUse big.py: resident, with caches |
18.2 ms | 19.7 ms |
PostToolUse big.py, changed before every call (40 rounds): one-shot |
117.5 ms | 122.8 ms |
PostToolUse big.py, changed before every call: resident, with caches |
47.6 ms | 50.1 ms |
- The client's start is the floor. Every hook call starts a process, about 15 ms here, before it can reach a daemon. Finding that no daemon listens costs nothing measurable.
- One git call is half of a small file's hook. PostToolUse reads the file's session-start text with
git cat-file blobto split old violations from new ones: about 15 ms per call on this machine. A daemon reads it once per session. - PostToolUse checks a file twice, as it is now and as it was at session start: 30 ms each for
big.py, warm. With a cache keyed by content, the start text is parsed once per session; an edited file still costs one parse. - Warm JIT counts too. A one-shot check costs 27 ms more than a warm one for
order.pyand 41 ms more forbig.py. The extra 14 ms is parsing and walking code that a fresh process hasn't optimised yet. - PreToolUse can't gain, at 16.8 ms against the 15.5 ms floor. Stop takes 141 ms but runs once per turn.
- Memory. The resident processes held 151 and 212 MB of RSS after the runs.
- Not measured: Windows named pipes, the compiled binary as the resident process, and Linux. The spike's scripts were throwaway and aren't in the repository; #60 adds the daemon to the benchmark job.
The hook daemon
#60 built the resident process the spike above measured, as ADR-039 decided: inwards daemon serves PostToolUse through a Unix socket (a named pipe on Windows), keeps extractions by text hash and git's answers by commit id, and reads everything else again on each request. The hook command itself is unchanged, so every PostToolUse still starts one process.
Method. The same arm64 laptop on macOS as the spike, the compiled inwards-darwin-arm64 with bytecode, load average 5 to 7 from other agents. examples/broken-app in a fresh git repository with a generated 4,492-line shop/domain/big.py holding two INW001 violations, after a SessionStart, so every finding is old and the hook reads each file's start text from git. One-shot (INWARDS_DAEMON=0) and through the daemon alternate in each round, with INWARDS_NO_CACHE=1; 80 rounds after 2 warm-ups, 40 when the file changes before every call.
| PostToolUse | One-shot p50 / p95 | Through the daemon p50 / p95 |
|---|---|---|
order.py, 13 lines |
38.0 / 39.3 ms | 15.3 / 16.2 ms |
big.py, 4,492 lines |
75.7 / 81.8 ms | 16.0 / 19.2 ms |
big.py, changed before every call |
76.1 / 79.0 ms | 26.8 / 36.8 ms |
- The target holds on this laptop. p95 is under 50 ms in every case, also for the large file that changes before every call, where the spike's prototype was at 50.1 ms.
- The bench job's synthetic repo, on the same laptop: 23.8 / 25.3 ms one-shot, 14.9 / 16.5 ms through the daemon (40 runs; no session, so no git read).
- Memory. The daemon held 188 MB of RSS after 206 hook runs over both files.
- Not measured here: Windows named pipes. CI runs the daemon's tests on Linux for every PR; the Windows and macOS rows run them only in the manual full matrix before a release.
A large file checked twice
#122 found the one-shot PostToolUse hook over the 100 ms budget on polar's server/polar/subscription/service.py (4,482 lines, two INW001 violations). The hook checks the edited file as it is now and again as it was at session start, to tell old violations from new ones, and a file with a violation needs a full parse each time. A CPU profile of one run (95 ms) put 43 ms in tree-sitter's two parses and 14 ms in the git cat-file blob that reads the start text.
What changed. The engine takes an optional TreeReuse (src/core/src/shared/python/reparse.ts) that keeps the last full parse. When the next full parse is of the same path, it describes the change between the two texts to tree-sitter as one edit (the span between their common prefix and suffix, in UTF-16 code units) and parses from the old tree, so only the changed region is parsed again. The CLI keeps one per process, and inwards daemon one for its whole life, so its next request on the same file reuses the last one. If the new tree has a syntax error, it is parsed again from scratch: error recovery can take another path when it starts from an old tree, and the first version of the test caught a case that did. The output doesn't change: src/core/test/python/reparse.test.ts compares every node with a fresh parse on hand-picked edits and on 12 seeded chains of 25 edits each, and a one-off run on 655 CPython 3.14 stdlib files with four stacked edits each and three seeds (7,860 parses, about half with syntax errors) found 0 differences in the trees, the imports or the suppression comments.
Method. An arm64 macOS laptop with 10 cores, the darwin-arm64 binary from develop (ec2bd65) against this one, both built by scripts/build-binaries.ts. Other agents were working on the machine (load average 4 to 10), so trust the ratios more than the milliseconds. polar at the corpus commit with the corpus layering, after a SessionStart, so both violations are old; "changed" means a line was added before every call. The two builds alternate in each round, 60 rounds after 2 warm-ups (40 for the daemon rows, which ran build by build).
polar subscription/service.py |
Before p50 / p95 | After p50 / p95 |
|---|---|---|
| PostToolUse one-shot, file unchanged since the session start | 99.8 / 101.8 ms | 84.6 / 87.5 ms |
| PostToolUse one-shot, file changed | 99.7 / 103.9 ms | 86.5 / 88.4 ms |
| PostToolUse through the daemon, file changed | 44.3 / 62.9 ms | 28.3 / 31.9 ms |
inwards check --no-cache on the file |
60.0 / 61.6 ms | 59.2 / 61.5 ms |
- The budget holds on this laptop for every path: p95 is under 100 ms one-shot and under 50 ms through the daemon.
- The second parse costs about 3 ms instead of about 16 ms for an edit of a few lines, measured in process on the same file.
- A one-file
inwards checkdoesn't change, since it parses once. Neither does a full check: no file is parsed twice there. - The bench job now times the hook on a 4,482-line module like polar's (
bench/large-file.ts). On the same laptop, 20 runs each: 102.0 / 104.1 ms before, 84.1 / 89.1 ms after one-shot, and 23.0 / 26.2 ms through the daemon. - On the Linux arm64 CI runner (4 cores), from the jobs of PR #299:
inwards check --no-cacheon polar's file took 62 and 65 ms p50 in two corpus runs and 128 ms in a third, where every repo ran about twice as slow. The bench job's hook on the 4,482-line module went from 117 to 101 ms p50 one-shot (median of pairs -17%) and took 19.3 / 27.4 ms through the daemon. On that runner the one-shot hook on a file this size is still over 100 ms; through the daemon it meets both targets. - What is left of the one-shot hook: about 15 ms of process start, 14 ms for the git read of the start text, and the first full parse.
Worker threads for a full run
#61 spread a cold full check over several threads. The decision and its alternatives are ADR-040.
What runs where. inwards check and inwards baseline start worker threads when they read 1,000 files or more: one thread per 500 files, up to INWARDS_THREADS or, unset, half of the cores beyond two, at most 4 (Linux below). The main thread counts as one of them. Workers do only what a file's text decides: the loader test, the import skeleton and the full parse's imports and suppression comments. The main thread walks the tree, reads the files, runs every rule in file order and parses the few files with dynamic imports itself. The output is the same byte for byte with any number of threads, and INWARDS_THREADS=1 keeps the whole check on one thread.
Method. The darwin-arm64 binary built by scripts/build-binaries.ts, the base build from develop (73936df) against this one, on an arm64 macOS laptop with 10 cores. Other agents were working on the machine, so the load average was 4 to 7: trust the ratios more than the milliseconds. Each case ran 11 times after one warm-up, every case once per round in rotating order, with INWARDS_NO_CACHE=1; each run's JSON had to match the base build's. The real repos are checked with the corpus layering (bench/corpus.json). Peak RSS is /usr/bin/time -l, three runs each.
| Repo | Files | Base | One thread | Four threads (default) | Eight threads |
|---|---|---|---|---|---|
| saleor | 4,324 | 1.48 s | 1.43 s | 0.98 s (1.51×) | 1.04 s |
| polar | 1,831 | 0.80 s | 0.76 s | 0.55 s (1.45×) | 0.55 s |
Synthetic (bench/generate.py) |
2,100 | 0.52 s | 0.49 s | 0.44 s (1.17×) | 0.48 s |
Synthetic legacy (--legacy, every module confirms) |
2,101 | 2.34 s | 2.31 s | 1.14 s (2.04×) | 1.03 s |
- One thread got faster too, by 2% to 5%: the check now resolves each file's real path once instead of twice.
- Parsing scales; the rest doesn't. With four threads, saleor spends about a third of its time walking the tree, resolving real paths and reading files before the engine starts, then about 120 ms in the rules and 100 ms confirming and reporting, all on the main thread. The legacy repo, where every module needs a full parse, gains the most.
- More threads stop paying early. Each worker compiles the grammar and warms its JIT up on its own, and a loaded machine has fewer free cores than it reports. Below 1,000 files the threads cost about as much as they save: 537 saleor files took 207 ms on one thread and 218 ms on three.
- Memory. Saleor's peak RSS went from about 360 MB on one thread to about 520 MB with four and 615 MB with eight.
- The cache and the hooks. A warm-cache check didn't change (0.95 → 0.91 s on saleor), the run that fills an empty cache got faster (2.6 → 2.05 s), and
bench/compare.tsmeasured the hook and the pre-write guard within 3% of the base, the full check 20.5% faster. -
Linux, and why the default leaves cores free. The first CI run of the bench job, on a Linux arm64 runner that reports 4 cores, measured the synthetic repo's full check 59% slower with four threads. The linux-arm64 binary in an Ubuntu 24.04 container on the same laptop, pinned to four or eight cores (
--cpuset-cpus), five runs each, gave these medians:Cores Repo 1 thread 2 3 4 4 synthetic 0.42 s 0.44 s 0.53 s 0.67 s 4 synthetic legacy 2.28 s 2.33 s (1.67 to 2.34) 1.54 s 1.77 s 8 synthetic 0.42 s 0.38 s 0.40 s 0.44 s 8 synthetic legacy 2.30 s 1.68 s 1.38 s 1.23 s Each thread runs its own JavaScript VM, and its JIT compiler and garbage collector run on threads of their own, so a thread per core starves the main thread. With two threads as the default on that runner, the bench job still measured the synthetic full check 19% slower. The default is now half of the cores beyond two, at most 4: one thread on 4 cores, three on 8 and four from 10, as on the laptop above. - Not measured: GitHub's hosted 4-vCPU
ubuntu-latestrunner and Windows.
The serial part of a full run
With four threads, saleor spent about a third of a cold check on the main thread before the engine started: walking the tree, resolving real paths and reading files. #281 cut that part. The output is the same byte for byte, and the walk finds the same files under the same module names.
What changed.
- One real path per directory, not two per file. The walk resolves each directory and each symlink with
realpath. A plain file gets its directory's real path plus the namereaddirgave it: a file that isn't a symlink adds no link, sorealpathwould only repeat what the walk already resolved. The check then reuses those real paths instead of resolving every file again. On saleor, the walk went from about 114 ms to 30 ms and the second round ofrealpath(about 75 ms) is gone. - The files are read in one batch. A check of 1,000 files or more asks for every file at once (
fs.promises.readFile), so the reads wait on the disk together: 4,324 saleor files in about 55 ms instead of 90 ms. A smaller check, and every hook, reads one file after another as before. - The workers start before the reads. The check counts its files before it reads them, so the pool starts first and the workers load the grammar while the main thread reads.
- Each worker holds two batches. A worker that finished a batch used to wait until the main thread, busy with a batch of its own, got back to its event loop to send the next one. Now the next one is already queued.
Method. As for the worker threads above: the darwin-arm64 binary, 11 runs per build after one warm-up, in rotating order, with INWARDS_NO_CACHE=1, every run's JSON compared with the others. The bases are #61's single-threaded base (73936df) and develop before this change (3dc5489, four threads). Other agents were working on the same laptop (load average 5 to 11).
| Repo | Files | #61 base (one thread) | develop (four threads) |
Now (four threads) | Now (one thread) |
|---|---|---|---|---|---|
| saleor | 4,324 | 1.59 s | 1.09 s | 0.87 s | 1.31 s |
| polar | 1,831 | 0.79 s | 0.57 s | 0.47 s | 0.67 s |
Synthetic (bench/generate.py) |
2,100 | 0.51 s | 0.43 s | 0.33 s | 0.40 s |
Synthetic legacy (--legacy) |
2,101 | 2.47 s | 1.23 s | 1.03 s | 2.34 s |
The #61 base measured 1.48 to 1.62 s on saleor across six sessions that day, and this change 0.74 to 0.87 s with four threads: 1.83× to 2.00×, with a median of 1.93×. That puts the 2× #281 asked for at the edge rather than clearly met. All runs of every build gave the same JSON.
Each change on its own. Builds that each leave one change out, on saleor, 11 runs each (load average 7 to 16): all four 744 ms; without the walk's real paths 861 ms, without the batch read 812 ms, with the pool started after the reads 776 ms, with one batch per worker 794 ms.
What didn't pay, and was dropped.
- Listing the layer links while the reads wait. macOS serialises the file system calls: the links walk took 76 to 102 ms during the reads instead of 21 ms after them, and the sum didn't change.
- Starting the workers on the files as they are read. Idle workers ran the skeleton jobs of each 256-file chunk as it came in, and the engine's call reused the answers to identical jobs. Saleor 775 → 792 ms, polar 475 → 478 ms, the synthetic repos within 1%: no gain worth a second queue in the pool.
- Fewer
realpathcalls on directories. The walk is bound byreaddir: 23 ms with or without them.
Linux. The linux-arm64 binary in an Ubuntu 24.04 container on the same laptop, seven runs each. Pinned to four cores, where the default is one thread, nothing changed: saleor 1.24 s before and after, polar 0.68 s, the synthetic repo 0.42 s, the legacy one 2.27 s. Linux answers realpath and file reads from its caches cheaply, so the serial part this removed was a macOS cost. Pinned to eight cores (three threads), saleor went from 0.92 to 0.87 s and the legacy repo from 1.43 to 1.37 s. The 3× on 4 vCPU that #61 asked for stays out of reach: a 4-core machine keeps one thread, and that thread spends its time in the parse and the rules.
What stays on the main thread. Timed from source on saleor with four threads: about 45 ms to walk and name the files, 70 ms to read them, then the engine: 260 ms for the skeleton batch (shared with the workers), 127 ms for the scans, 135 ms for the full-parse batch (shared), 60 ms to confirm and report and 33 ms for the whole-run checks. The scans and the confirmations are the rules, which stay on one thread by design (ADR-040).
Precision of the opt-in rules
The opt-in content rules (INW012 to INW016, FAPI001 to FAPI009) shipped with tests on fixtures only. #182 turned them on over the five corpus repos at their pinned commits, triaged the findings by hand, fixed the largest false-positive classes, and timed each rule.
Method. Each repo ran with its manifest layering plus select of every opt-in rule. INW015 needs a role, so fastapi-clean-example got role = ["app.outbound"], allowed-in = ["app.main"] and python-ddd role = ["modules.*.infrastructure", "seedwork.infrastructure"], allowed-in = ["config", "api.main", "cli"]. Polar's routers come from a class built at run time (#358), so INW012 saw one of its 450 endpoints until a second run added decorators = ["polar.*.router.get", "polar.*.router.post", "polar.*.router.patch", "polar.*.router.put", "polar.*.router.delete"]. A finding is a true positive when what it claims is true and a reader of the rule's page would want it fixed; a finding that is true to the letter but not worth fixing, such as a health check that pings the database, counts as false. Where a rule had more findings than could be read, every fifth one was looked at.
| Rule | Findings before → after | Looked at | Precision before → after | Fix in #182 |
|---|---|---|---|---|
INW012, Polar with decorators |
108 → 73 | 22 before, 25 after | 36 % → 68 % | any raise is a guard; loader options aren't denied calls |
| INW012, the other repos | 4 → 4 | all | 3 of 4 | none needed |
| INW013 | 1 → 1 | all | 1 of 1 | none needed |
| INW014 | 0 → 0 | n/a | n/a | none needed |
| INW015 | 48 → 17 | all | 31 % → 88 % | exception classes of the role aren't reported |
| INW016 | 173 → 152 (55 after #361) | every column finding and table name | 88 % → 100 % against the default scheme | Alembic migrations aren't read |
| FAPI001 | 22 → 21 | all | 86 % → 90 % | an app with openapi_url=None has no schema |
| FAPI002 | 18 → 17 | 8 | all true | the same |
| FAPI007 | 4 → 0 | all | 0 % → no findings | a generator that yields twice or in a loop is a stream |
| FAPI003, FAPI005, FAPI006, FAPI008, FAPI009 | 0 → 0 | n/a | n/a | none needed |
What the false positives were, and what is left:
- INW012. 8 of the first sample's 14 false positives were guards that raise the project's own errors (
raise ResourceNotFound(), mapped to 404 by an app-wide exception handler); counting them as guards lost one true positive, a business rule written as two guards. 3 across both samples were a singlejoinedload(...)passed to a repository. Left: server-rendered HTML in nestedwithblocks (46 of the 73 findings are in Polar's back office), HTMX form handlers, health checks and a webhook (#360). The default thresholds held: only 3 of the 73 findings trip a single signal by 2 statements, 1 branch or 1 level or less. #360 then counted a tree of markupwithblocks as one statement, aniforexceptthat shows one message and returns as a guard, and left health checks alone. With every Polar router recognised (#358), that took Polar from 135 findings to 109 and the every-fifth sample from 10 of 27 true (37 %) to 10 of 22 (45 %), losing no true positive; Saleor kept its 2 (INW012's page has each change on its own). The thresholds stay: of the 12 false positives left, 2 are within 2 statements of the limit, and raisingmax-statementsto 12 would clear those 2 and no sampled true positive, too few findings to move a default. - INW015. 31 of 48 findings imported an exception class from an adapter to map it to an HTTP status. Left: a constant imported from an adapter. A test module was the other false positive; since #362 the content rules skip test modules, which leaves 16 findings, 15 of them true.
- INW016. 21 findings repeated a model's column in an Alembic migration. The 152 left are correct against the default scheme, but 98 are Polar's plural table names, 94% of its 104. #361 reports such a scheme once in a whole-project run, naming
table-name = "snake": Polar went from 121 findings to 24 and the corpus from 152 to 55. Saleor's 26 stay: 46 of its 72 datetime columns end with_at, so itsdate_joinedandstart_dateare a mix, not a scheme. 13 column findings no longer suggest a name made of time words only (date_at,timestamp_at), anddate_of_birthnow getsbirth_date. - FAPI001, FAPI002. Polar's back office is a
FastAPI(openapi_url=None)app. The two FAPI001 findings on test apps in Polar are gone since #362, which leaves 19, all true. Both rules saw about 40 endpoints in the corpus, because Polar's and fastapi-clean-example's routers weren't recognised (see below). - FAPI007. All 4 findings were streams (Polar's server-sent events, Saleor's discount iterator), not dependencies.
Routers built at run time. #358 taught the FastAPI model and INW012 the routers the run above missed: Polar's APIRouter = get_api_router_class(APIRoute) and BackofficeRouter = get_api_router_class(TransactionalAPIRoute), and fastapi-clean-example's routes declared inside make_*_router() -> APIRouter factories. The name is resolved through the project's imports instead of trusting any callee called APIRouter, since OpenStack projects name their WSGI routers that (the rule pages list what counts). Same method, rerun on 2026-10-11 against develop at a8c282a, which skips test modules (#362); path operations are counted outside tests:
| Rule, repo | Path operations seen | Findings before → after | Looked at | Precision after |
|---|---|---|---|---|
| FAPI001, Polar | 1 → 526 | 0 → 131 | all classified; the 35 on public routes read | 25 of 131 (19 %); 25 of the 35 on public routes (71 %) |
| FAPI001, fastapi-clean-example | 4 → 15 | 0 → 0 (11 before description= counted as a docstring) |
all | no findings |
| FAPI002, Polar and fastapi-clean-example | as above | 0 → 0 | n/a | n/a |
INW012, Polar (no decorators) |
1 → 526 | 1 → 135 | 27, every fifth | 10 of 27 (37 %) |
| INW012, fastapi-clean-example | 4 → 15 | 0 → 0 | n/a | no findings |
| FAPI003, Polar | as above | 0 → 0 (72 warnings before the fix below) | all | n/a |
| FAPI005, Polar | as above | 0 → 0 (2 before the fix below) | all | n/a |
full-stack-fastapi-template and python-ddd didn't change, and Saleor wasn't rerun. What the new findings are:
- FAPI001. 96 of Polar's 131 are on routes tagged
APITag.private, which Polar's route class keeps out of its production schema (read since #392, below). Of the 35 on public routes, 10 are false: 4 CSV exports and 6 OAuth2 endpoints whose bodies RFCs define. fastapi-clean-example's 11 were routes withdescription=getdoc(...); FastAPI reads a docstring only whendescription=is absent (Path Operation Configuration), sodescription=now counts as one. A router that every followed inclusion puts under aFastAPI(openapi_url=None)app stays hidden when another inclusion can't be followed; without that, Polar's back office added 115 false findings. - FAPI002. Still silent on both: Polar includes its API router through a parameter of
add_versioned_routers(app, api_router, ...)and some routers through factory calls, and fastapi-clean-example includes every router through a factory call, so the inclusions above their routes are unknown. #391 follows them (below). - INW012. 107 of Polar's 135 findings are in the back office; the 17 false ones in the sample are 15 server-rendered pages and HTMX form handlers there, a server-sent event stream and a webhook (#360).
- FAPI003, FAPI005. Recognising more routers first added false alarms: FAPI003 warned that 72 of Polar's routers were unmounted, because the same unknown inclusions hide how they are wired (followed since #391, below), and FAPI005 reported 2 routes Polar's route class dispatches by API version (#392). A router a first-party class or factory builds is now unknown to both: FAPI003 skips it while an inclusion it can't follow could include it or a router above it (a factory call only the routers that factory returns, any other target any router), and FAPI005 doesn't read its route order. Routers FastAPI's own constructor builds keep the older answers.
The cost, from source on the laptop above, median of 3 cold runs on Polar with one rule on: INW012 1,118 → 1,401 ms, FAPI001 1,195 → 1,457 ms, FAPI002 1,188 → 1,725 ms (base develop at c38c5ae), for the 525 more path operations each rule now reads.
Inclusions through parameters and factories. #391 follows one hop of first-party code: app.include_router(api_router) inside a function, to what each call of the function passes, and include_router(make_router()), to the router the factory returns (FAPI003's page has the rules). Same method, Polar, fastapi-clean-example and full-stack-fastapi-template rerun on 2026-10-11 against develop at cf127b7 with FAPI001 to FAPI009 on:
| Repo | Inclusions not followed, before → after | Routers with routes no app reaches | Findings before → after |
|---|---|---|---|
| Polar | 6 → 0 | 0 | FAPI001 131 → 131, FAPI002 0 → 1, FAPI003 and FAPI005 0 → 0 |
| fastapi-clean-example | 16 → 0 | 0 | none before or after |
| full-stack-fastapi-template | 0 → 0 | 0 | unchanged (FAPI001 13, FAPI002 16) |
- FAPI003. With every inclusion followed, FAPI003 judges Polar's 72 routers instead of skipping them as unknown, and an app reaches each one: no finding, and none of the 72 false "unmounted" warnings the #358 run showed before its fix.
- FAPI001. Following
add_versioned_routers(app, api_router)puts Polar's API routes undercreate_app()'sFastAPI(openapi_url=None), which hid all 131 findings. FastAPI'sopenapi_url=Noneonly stops FastAPI serving the schema; Polar serves/{version}/openapi.jsonitself from the same routes. An app that adds a route of its own ending inopenapi.jsonnow counts as serving a schema, which brings back the same 131 findings, and Polar's back office (no such route) stays hidden. - FAPI002. Polar's 1 finding is true: OAuth2
authorizeraises 401 and declares no responses. Most of its other routes raisePolarErrorsubclasses, mapped by handlers registered inadd_exception_handlers(app), a parameter FAPI002 doesn't follow, and answeringexc.status_code(#400). fastapi-clean-example's routers are built by a factory around a third-partyErrorAwareRouter, whose keywords are unknown, so its declared responses are too.
Cost: 9 cold runs on Polar with every FAPI rule on, alternating with develop at 9ac26f7 (after #402): median 1,565 ms before and 1,619 ms after, fastest run 1,466 and 1,487 ms, within this laptop's noise. The project scan for a function's calls parses only the files that spell its name.
Route classes. #392 reads what a router's route class does, from route_class= or a first-party router class that sets it (FAPI001's page and FAPI005's have the rules). The issue weighed three options: a per-rule option naming the tags that keep a route out of the schema, treating every first-party route class as unknown, or leaving it to modules and suppressions. Reading the class's own code needs no configuration and stays silent wherever it can't read the class, so that is what shipped. Same method, Polar on top of #391:
| Rule, Polar | Findings before → after | Looked at | Precision before → after |
|---|---|---|---|
| FAPI001 | 131 → 30 | all | 19 % → 67 % (20 of 30) |
| FAPI002 | 1 → 1 | all | 1 of 1 |
| FAPI005 | 0 → 0 | n/a | n/a |
- FAPI001. Polar's
IncludedInSchemaAPIRoutesetsinclude_in_schematosettings.is_development()for a route taggedAPITag.private,TrueforAPITag.publicandFalseotherwise, private checked first. All 101 findings that went away are on private routes: the 96 counted above, and 5 the #358 count put among the public ones, which carrytags=[APITag.private]on the decorator under a public router. The 10 false positives left are the same 4 CSV exports and 6 OAuth2 endpoints whose bodies RFCs define. Polar's 77 API routers read as "schema by tags"; its 22 other apps and routers use FastAPI's defaults. - FAPI005. The 77 API routers' route class includes
VersionedAPIRoute, which overridesmatches, so their order stays unread, and the 2 version-split pairs inwebhook/endpoints.pystay silent. Before, every router a first-party class built was unread (#358). Now the back office's routers, whose route class isTransactionalAPIRoute(it only wraps the handler), are read too, with no findings.tests/kit/test_versioning.py's 3 pairs are in a test module, which the corpus layering ignores. - fastapi-clean-example and full-stack-fastapi-template didn't change: their routers use FastAPI's route class or come from factories.
Cost. Every rule alone on top of the manifest layering, cold (--no-cache) and warm, median of 5 runs (3 for polar and saleor), with the darwin-arm64 binary on the laptop above while other agents ran (load average 5 to 11). Milliseconds, cold / warm:
| Rule | template | clean-example | python-ddd | polar | saleor |
|---|---|---|---|---|---|
| none | 44 / 34 | 75 / 55 | 82 / 77 | 603 / 501 | 931 / 1,034 |
| INW012 | 79 / 79 | 93 / 84 | 91 / 83 | 1,119 / 955 | 1,284 / 1,117 |
| INW013 | 43 / 38 | 115 / 116 | 113 / 113 | 7,826 / 7,246 | 954 / 924 |
| INW014 | 42 / 34 | 77 / 60 | 82 / 80 | 592 / 499 | 923 / 907 |
| INW015 | n/a | 105 / 106 | 113 / 125 | n/a | n/a |
| INW016 | 49 / 44 | 80 / 61 | 90 / 88 | 778 / 619 | 1,187 / 1,251 |
| FAPI001 | 79 / 79 | 81 / 88 | 109 / 105 | 1,299 / 1,173 | 1,357 / 1,319 |
| FAPI002 | 89 / 89 | 88 / 81 | 109 / 108 | 1,426 / 1,180 | 1,481 / 1,475 |
| FAPI007 | 65 / 64 | 81 / 75 | 91 / 91 | 1,326 / 1,197 | 1,362 / 1,490 |
| every opt-in rule | 130 / 130 | 175 / 189 | 178 / 171 | 9,299 / 9,157 | 2,089 / 2,189 |
The other FAPI rules cost about what FAPI001 does. The warm column barely differs, because the extraction cache holds imports, not the trees the content rules parse. Three costs stood out:
- INW012 on Saleor took 8.0 s, against 1.1 s without it (both run from source): nearly every file mentions Django, so each got a full parse, and each class with a first-party base read that base's module. A Django file now needs a view's shape before the parse (
@api_view,@action,path(...),re_path(...)or adef get(-style handler method, unlessmodulesscopes the rule), and only a class with a handler method resolves its bases. Saleor with INW012 went to 1.3 s, with the same 2 findings. - INW013 on Polar took 7.8 s, about 13 times the check without it: a hop into another module parsed that module again for every file that called into it. Since #359, each module a hop reads is parsed and read once per run, a call to a method of a module-level object (
service.create(...)) reads nothing, a checked file a hop already parsed isn't parsed again, and the walks over a function body run inside WASM. Measured before and after in one sitting, alternating the two binaries, median of 5, cold / warm: Polar with INW013 went from 7,238 / 6,971 ms to 3,526 / 3,182 ms, and with every opt-in rule from 8,790 / 9,068 ms to 4,984 / 5,052 ms, against 454 / 321 ms with none. The other four repos moved by less than 10 ms, and the JSON findings are identical. That left about 3 s: 865 of Polar's 1,831 files have anasync def, and each got a full parse. Since #369, a run where at least 200 files, and one in 20, have anasync defreads every listed module's text once, parses only the modules whose imports can spell a blocking type (22 on Polar), and skips a checked file that names neither a blocking type nor one of their blocking helpers or its aliases. Same method, basedevelopat 06c400d, cold / warm: Polar with INW013 went from 3,643 / 3,507 ms to 729 / 549 ms, against 548 / 353 ms without it (+33 %), and with every opt-in rule from 5,270 / 4,963 ms to 2,329 / 2,105 ms. Saleor (12 files with anasync def) and the three small repos stay below the threshold and moved by less than the noise, and the one-file check ofsubscription/service.pystayed at 153 ms. The JSON findings are identical on all five repos, and on a copy of Polar with blocking helpers called through renaming re-exports, module aliases, relative imports and a passedSession. - Every opt-in rule on Polar still took 2.3 s after #369, about 5 times the check without them: INW012, INW014, INW015, INW016, FAPI007 and the FastAPI model each parsed the files they read on their own, 848 parses of 450 distinct files. Since #387, a run parses each text once (
ModuleTrees.treeOf), whichever of those rules or a hop into another module asks first, and frees every tree when the run ends. Polar now makes 450 full parses on the main thread (about 490 ms of parse time). Same method, basedevelopat 0596d16, median of 7, cold / warm: Polar with every opt-in rule went from 2,343 / 2,256 ms to 1,925 / 1,789 ms, against 455 / 322 ms with none, so 4.2 times the check without them, not the 2 times #387 aimed for. Parsing those 450 files alone costs about what the check without the rules does, and the rules' own work (the FastAPI model and graph, INW012's views) is most of the rest; going further needs the content rules off the main thread or cheaper rule code. Peak RSS stayed within the noise (567 to 574 MB). Saleor (2,102 to 2,067 ms cold) and the three small repos (10 to 15 ms faster) moved little, and the one-file checks ofsubscription/service.py(176 to 158 ms) andsubscription/endpoints.py(84 to 78 ms) got faster. The JSON findings are identical on all five repos, with no opt-in rule and with every one. - Every opt-in rule on Polar took 2.4 s again after #394 taught the model Polar's router class built at run time: the rules read 525 more path operations, and FAPI001 builds the router graph for them. A CPU profile of that run (
bun --cpu-prof) showed about 0.65 s of parsing on the main thread and the rest spread over the rules. Since #395, four costs are gone. FAPI002 followed nearly every call in an endpoint into the module that defines its receiver (items.load(...)into the service module) and parsed that module only to find the name isn't imported there; the model now reads such a module's imports from its import skeleton and parses it only when an import binds the name, which skips 123 of the model's 329 parses on Polar. A function's return annotation is resolved only when the function returns a name the file uses as a router, since-> Subscriptionparsed the models. INW012 built its views of other modules once per checked file and now builds them once per run (ThinEndpointRun). The FastAPI model, INW012, INW016 and FAPI007 walked each shared tree for calls, assignments and definitions several times;moduleNodeswalks a tree once for all five node types and keeps the lists while the tree lives. darwin-arm64 binaries, basedevelopat cf127b7, alternated, median of 7, cold / warm: Polar with every opt-in rule went from 2,443 / 2,352 ms to 1,901 / 1,795 ms, against 474 / 319 ms with none, so 4.0 times the check without them, still short of the 2 times #395 asks for. Parsing the files the rules need costs about 0.5 s on the main thread, which is more than a 2-times budget leaves for all of the rules' work, so going further needs the content rules on the worker threads. Saleor went from 1,286 to 1,167 ms cold (770 ms with none), and the three small repos got 11 to 14 ms faster. Peak RSS stayed within the noise (670 to 647 MB on Polar). The one-file check ofsubscription/endpoints.pywent from 831 to 658 ms and its PostToolUse hook from 1,608 to 1,256 ms, both still far over the hook budget because FAPI001 builds the whole router graph for that file;subscription/service.pystayed at 156 ms. The JSON findings are identical on all five repos, with no opt-in rule and with every one.
The hook. #182 asked for no measurable hook regression on files without endpoints and one full parse at most on files with them. inwards check --no-cache <file>, 21 alternating runs each, milliseconds p50 / p95:
| File | Endpoints | INW012 off | INW012 on |
|---|---|---|---|
saleor order/actions.py (2,110 lines, mentions Django) |
none | 33 / 35 | 33 / 35 |
polar subscription/service.py (4,482 lines) |
none | 60 / 61 | 61 / 64 |
saleor thumbnail/views.py |
none (its 2 views are registered in urls.py) |
32 / 33 | 33 / 34 |
polar subscription/endpoints.py (decorators set) |
9 | 29 / 31 | 43 / 50 |
template api/routes/items.py |
5 | 26 / 27 | 32 / 34 |
Before the Django prefilter, order/actions.py took 53 / 54 ms with INW012 on. A file with endpoints pays one full parse, which the prescan otherwise skips.
Performance roadmap
| Step | Expected effect | Targets |
|---|---|---|
inwards daemon: a resident process per project that PostToolUse reaches through a local socket, with fallback to a one-shot run; the language server stays a separate process, inwards server (ADR-039, #60), done |
Measured (above): PostToolUse p95 39.3 → 16.2 ms for a 13-line file, 79.0 → 36.8 ms for a 4,492-line file edited before every call | Single-file p95 |
| Incremental parse of a file checked twice: the hook's check now and at session start, the daemon's next edit (#122), done | Measured (above) on polar's 4,482-line file: PostToolUse p95 103.9 → 88.4 ms one-shot, 62.9 → 31.9 ms through the daemon | Single-file p95 |
bun build --bytecode (#39), done |
Measured: start-up 22 → 10 ms, hook call about 45% faster, 2.5 MB more per binary (see the spike above) | Single-file p95 |
| Worker threads for a cold full run (#61, ADR-040), done | Measured with four threads (see the section above): saleor 1.48 → 0.98 s, polar 0.80 → 0.55 s, the synthetic repo 0.52 → 0.44 s, the legacy one 2.34 → 1.14 s. Short of the 3× hoped for, because reading the files and the rules stay on one thread | Cold full run |
| Cheaper serial part of a full run: real paths per directory, one batch read, workers started before the reads, two batches per worker (#281), done | Measured with four threads (above): saleor 1.09 → 0.87 s, 1.8 to 2.0× faster than one thread before #61. No change on Linux with four cores | Cold full run |
Content-hash cache of import lists (.inwards/cache, #56), done for inwards check and inwards baseline |
Measured: a warm full check 3.0 times faster (0.46 s against 1.25 s p50, 12 runs each on this laptop under load), 27% slower while it fills. The hooks don't use it (ADR-031) | Warm full run |
Tree-cursor walk instead of descendantsOfType on the full-parse path (#62), done |
Measured on 2,100 synthetic files, cold, 10 alternating runs each: 13% faster when every file needs a confirmation (3.34 → 2.90 s p50), 10% faster when the prescan refuses every file (3.13 → 2.80 s). Reading the imports and suppression comments of the 1,059 stdlib files went from about 560 ms to 125 ms. The one-file hook and the clean full check don't change | Refused files and confirmations |
Reproduce
bun install
bun test                                                    # 2,500+ tests: unit, CLI, hook, Stop gate, baseline, stats, E2E snapshots, doc snippets, bench
bun run scripts/build-binaries.ts bun-linux-x64
python3 bench/generate.py /tmp/inwards-bench
(cd /tmp/inwards-bench && "$OLDPWD/dist/inwards-linux-x64" check)  # 2100 files, 0 violations, ms
bun run src/core/scripts/prescan-diff.ts "$(python3 -c 'import sysconfig; print(sysconfig.get_paths()["stdlib"])')"
bun run bench/corpus.ts --bin dist/inwards-linux-x64 --dir ~/.cache/inwards-corpus  # real-repo corpus, about 90 s
bench/corpus.ts reuses a checkout that is already at its pinned commit, so later runs download nothing. To add a repo, append it to bench/corpus.json with a full commit SHA, its .py count and a layering; the PR runs the corpus workflow.
Two checks keep the agent-facing tests honest. A code fence in docs/chapters/guides or docs/chapters/rules that follows a <!-- e2e --> line and one blank line (without it, the comment breaks a list item) runs as an E2E case in a fresh project, against the compiled binary in CI (src/cli/test/integration/docs.test.ts); untagged fences are never run. The fences run in the system's bash, which on macOS is bash 3.2, so the harness never puts a heredoc inside $(...): bash 3.2 matches quotes across it, and one apostrophe in a documented message breaks the script. Every night, .github/workflows/nightly-e2e.yml records the Claude Code hook payloads again with a headless claude -p session and opens an issue when a field is added, removed or changes type against the recorded fixtures.
The screenshots in these docs come from scripts/screenshots.py, which runs each command for real and renders the terminal output with Rich.
Risks
| Risk | Likelihood | Impact | Mitigation |
|---|---|---|---|
| Astral ships layer contracts in ty or Ruff | Medium | High | Compete on agent integration and fix quality, which aren't Astral's focus. Keep the rules format simple enough to export |
| import-linter adds JSON output and agent hooks | Medium | Medium | Stay ahead on latency, a standalone binary and per-violation fixes. Keep switching one command: inwards import-config converts import-linter contracts (guide) |
| Real repos break the 100 ms p95 | Happened: a 4,482-line polar file with violations took 125 to 280 ms before bytecode compilation, and its one-shot hook about 104 ms p95 locally after. Now 88 ms one-shot and 32 ms through the daemon (#122) | High | inwards daemon (ADR-039) and an incremental second parse, both done; the bench job times a file of that size on every PR. Then a Rust/Zig WASM prescan (the fallback in ADR-001) |
| The prescan misses an import on some unusual file | Low | High | Differential test in CI on the stdlib, nightly on five real services; grow that corpus with repos from design partners |
Agents edit [tool.inwards] to pass |
High without a guard | High | PreToolUse config guard, the Stop gate's config comparison, permissions.deny rules from init, CODEOWNERS (chapter 4). Bash can still get past the guard; a replayed session start is caught by the start record's copy outside the project, unless the agent deletes that too, and a Stop hook removed through Bash is only reported at the next session start (#88) |
Bun --compile regressions or breaking changes |
Low | Medium | Pinned via .bun-version; the CD verify matrix runs every binary |
| A binary silently ignores its bytecode (Bun falls back to parsing the source) and start-up doubles | Low | Low | Tests still pass in that case; the PR benchmark catches it on Linux only. Bytecode is tied to the Bun version that built it, and every binary embeds that same version |
| The self-hosted part of CI is unavailable and the PR jobs that run there queue | Medium | Medium | To save GitHub Actions limits and costs, some automated CI jobs run on self-hosted infrastructure; when it is unavailable, those jobs can run on GitHub-hosted runners instead |
| Zensical (0.0.x) changes its config format | Medium | Low | Docs build runs in CI on every PR; the config is small |
| Fix steps are wrong for unusual layouts (no obvious place for a port) | Medium | Medium | Measure fix-within-one-retry per rule; let the config name the ports module |